4 Dot plots
TipTheme:
theme_blockbuster()
Graphs in this chapter use fmggp2::theme_blockbuster(), modeled on a Blockbuster Video store: royal blue background, yellow ticket stub marks, white Arial text, and an Impact title.
4.1 Description
A dot plot displays each data point as a dot on a single axis, making it useful for identifying patterns, gaps, and outliers in small to moderate datasets. Each dot represents an observation in the data, stacked over categories or spread along a number line.
In ggplot2, we can build dot plots with geom_dotplot().
4.2 Set up
PACKAGES:
Install packages.
show/hide
library(ggplot2)
library(dplyr) # for tibble() and data manipulation
DATA:
In the late 90s, most Friday nights started at Blockbuster Video.

We’ll simulate how many movies 60 households rented in one week with rpois(), which generates whole number counts (0, 1, 2, and so on). Setting the seed with set.seed() means you’ll get the same 60 households every time you run the code below.
show/hide
set.seed(1993) # same 60 households every time the code runs
blockbuster_rentals <- tibble(
  household_id = 1:60, # 60 different households, one row each
  rentals = rpois(n = 60, lambda = 3) # weekly rentals (about 3 on average)
)
glimpse(blockbuster_rentals)
#> Rows: 60
#> Columns: 2
#> $ household_id <int> 1, 2, 3, 4, 5, 6, 7, 8, 9, …
#> $ rentals      <int> 2, 0, 2, 4, 3, 3, 2, 2, 5, …
4.3 Distribution
Rentals are counts: a household rents 0, 1, 2, or more movies, but never 2.5. Dot plots are a good fit for counts like these because each dot is one household, so the graph is just the data stacked into piles.

Because we picked the rental rate in rpois(), we know what the piles should look like before we draw them. Below we’ll move from the counts, to a picture, to the formula.
COUNT IT:
Start with the first ten households.
show/hide
head(blockbuster_rentals$rentals, 10)
#>  [1] 2 0 2 4 3 3 2 2 5 0
Most of these households rented two or three movies, two rented none, and one rented five. If we count all 60 households, we can compare each pile to the number of households we’d expect (we’ll see where dpois() comes from below).
show/hide
blockbuster_rentals |>
  count(rentals) |>
  mutate(expected = round(60 * dpois(rentals, lambda = 3), 1))
The observed piles stay close to the expected ones. Counts like these have one more property worth checking: the mean and the variance should be about the same.
show/hide
blockbuster_rentals |>
  summarise(mean = mean(rentals), variance = var(rentals))
DRAW IT:
The dot plot below stacks one dot per household above its number of rentals. The tallest piles sit at two and three rentals, and the piles get shorter on both sides. The dashed line marks the rental rate we used in rpois() (3 per week). The right side trails out further than the left because a household can’t rent fewer than zero movies.
show/hide
ggplot(data = blockbuster_rentals,
    aes(x = rentals)) +
  geom_dotplot(binwidth = 1, dotsize = 0.3) +
  geom_vline(xintercept = 3, linetype = "dashed", color = "white") +
  scale_x_continuous(breaks = 0:7) +
  labs(x = "Number of rentals")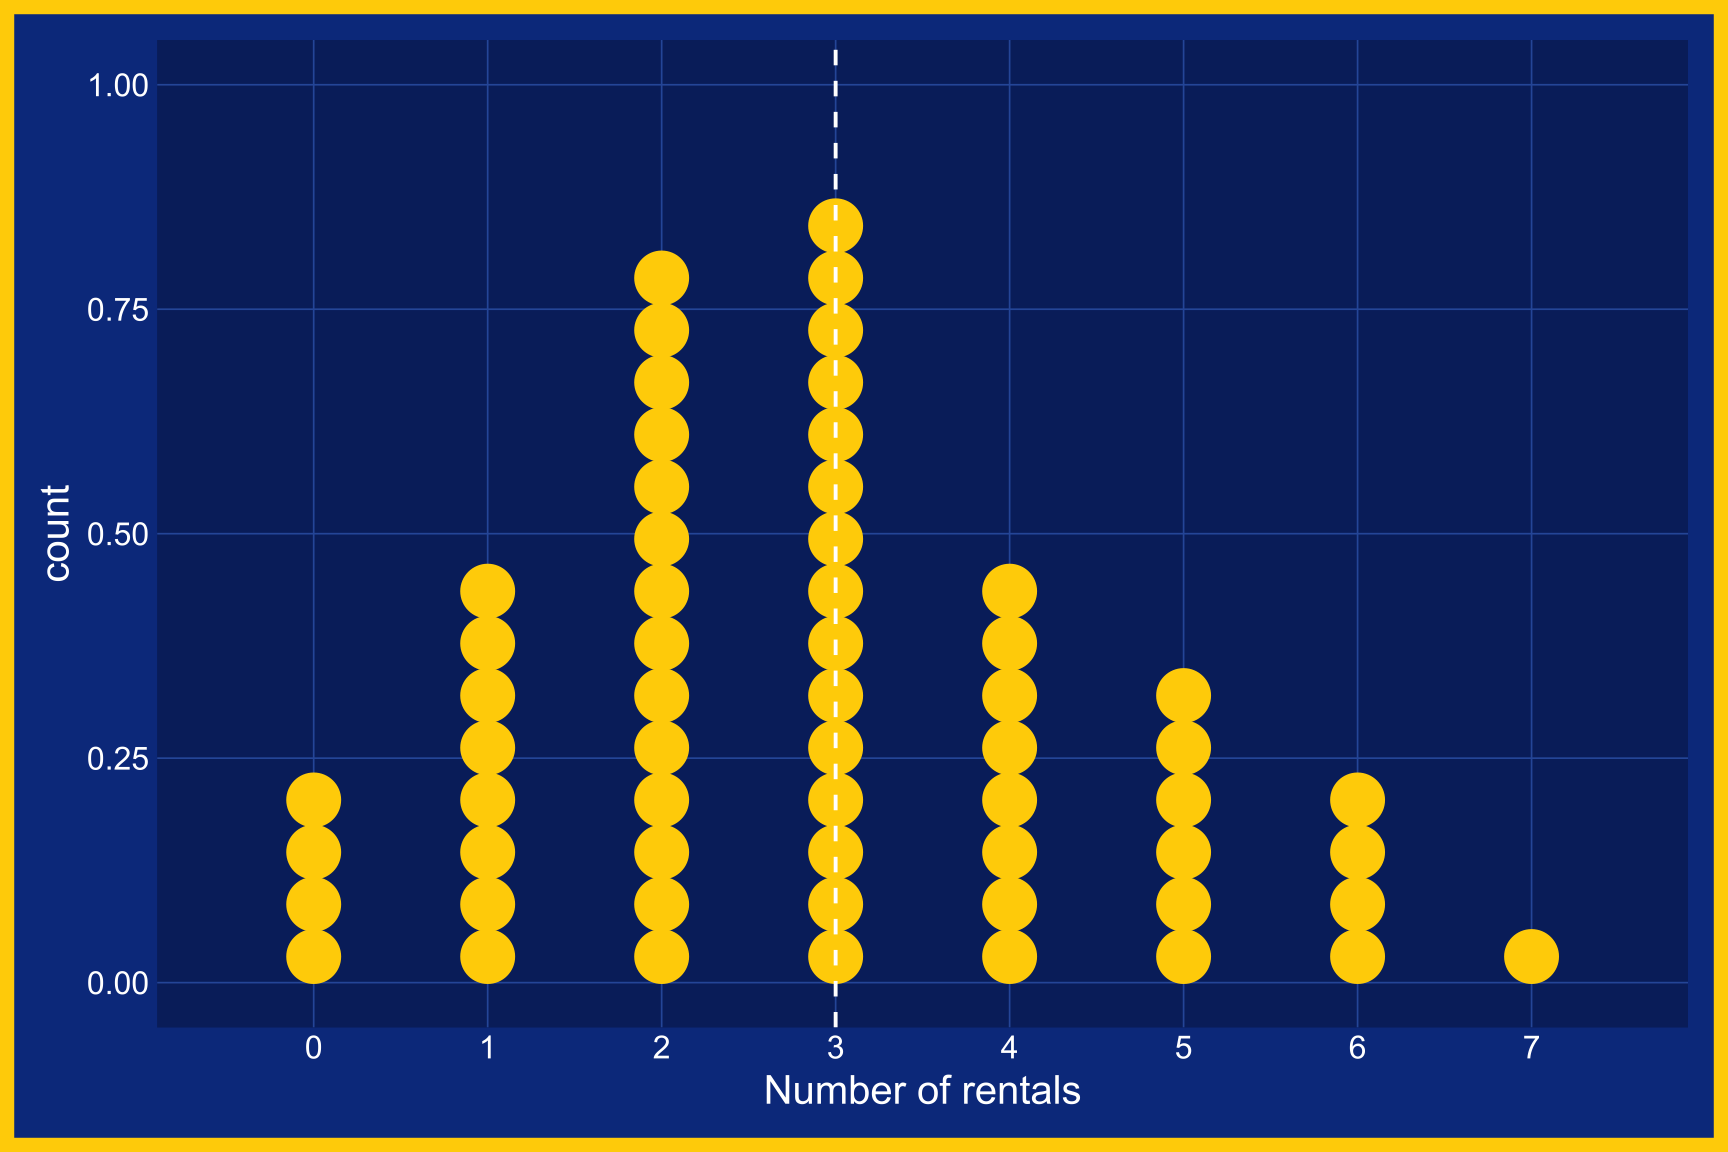
NAME IT:
The rpois() call that created the data is a single statement:
\[ X \sim \text{Poisson}(\lambda = 3) \]
The Poisson distribution describes counts of events in a fixed window of time (here, rentals in one week). It has a single parameter, the rate (\(\lambda\)), which is both the mean and the variance. That’s why our simulated mean (2.9) and variance (2.8) are so close.
The chance of a household renting exactly \(k\) movies is:
\[ P(X = k) = \frac{\lambda^k e^{-\lambda}}{k!} \]
This is what dpois() calculates. For \(k = 3\), \(P(X = 3) = 3^3 e^{-3} / 3! \approx 0.224\), so we’d expect about \(60 \times 0.224 \approx 13\) of our 60 households to rent three movies. We got 15. Try a larger lambda in rpois() and the piles move right and spread out, because the mean and the variance grow together.
4.4 Grammar
CODE:
Create labels with
labs()Initialize the graph with
ggplot()and providedataMap
rentalsto thexaxisAdd the
geom_dotplot()layerSet the
binwidthto1(one pile per number of rentals) and adjust thedotsizeSet the
xaxis breaks withscale_x_continuous(breaks = 0:7)
show/hide
labs_dotplot <- labs(
  title = "Blockbuster Video",
  caption = "Simulated data",
  subtitle = "Rentals per household in one week",
  x = "Number of rentals")
ggp2_dotplot <- ggplot(data = blockbuster_rentals,
      aes(x = rentals)) +
    geom_dotplot(binwidth = 1, dotsize = 0.2) +
    scale_x_continuous(breaks = 0:7)
ggp2_dotplot +
  labs_dotplot
GRAPH:
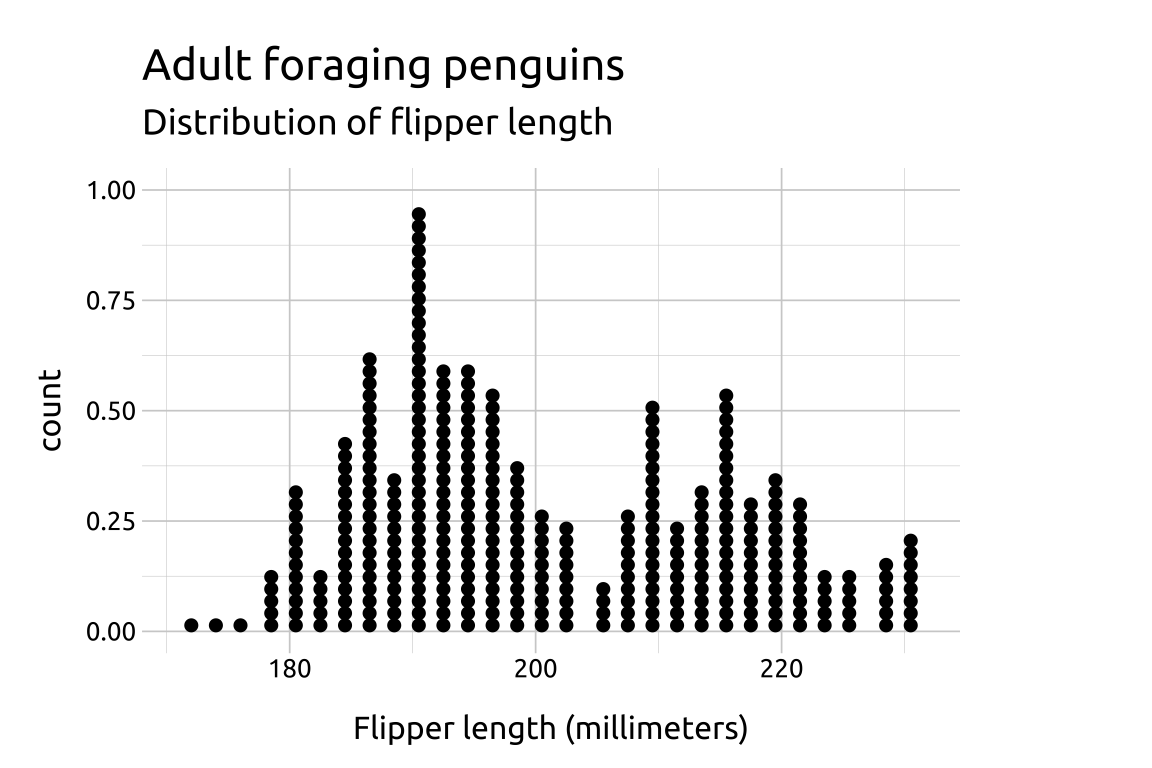
A downside of dot plots is that the y axis is hard to interpret.1 The axis is labeled count, but its numbers run from 0 to 1, even though the tallest pile in our graph holds 15 households.
These numbers don’t line up with the piles because geom_dotplot() doesn’t put counts on the y axis. It sizes each dot as a fraction of the binwidth (with dotsize = 0.2, each dot is a fifth of one rental wide). Then it stacks the dots on top of each other until the pile runs out. The height of a pile depends on how many dots it holds and how big each dot is, so changing dotsize makes every pile taller or shorter without changing the data. The y axis isn’t measuring anything; it’s just leftover space for the dots to sit in.
The number of households is still in the graph, but we read it by counting the dots in each pile, not by looking across to the axis. Because the axis can mislead readers, it’s common to hide it with scale_y_continuous(NULL, breaks = NULL).
show/hide
labs_dotplot <- labs(
  title = "Blockbuster Video",
  caption = "Simulated data",
  subtitle = "Rentals per household in one week",
  x = "Number of rentals")
ggp2_dotplot <- ggplot(data = blockbuster_rentals,
      aes(x = rentals)) +
    geom_dotplot(binwidth = 1, dotsize = 0.2) +
    scale_x_continuous(breaks = 0:7) +
    scale_y_continuous(NULL, breaks = NULL)
ggp2_dotplot +
  labs_dotplot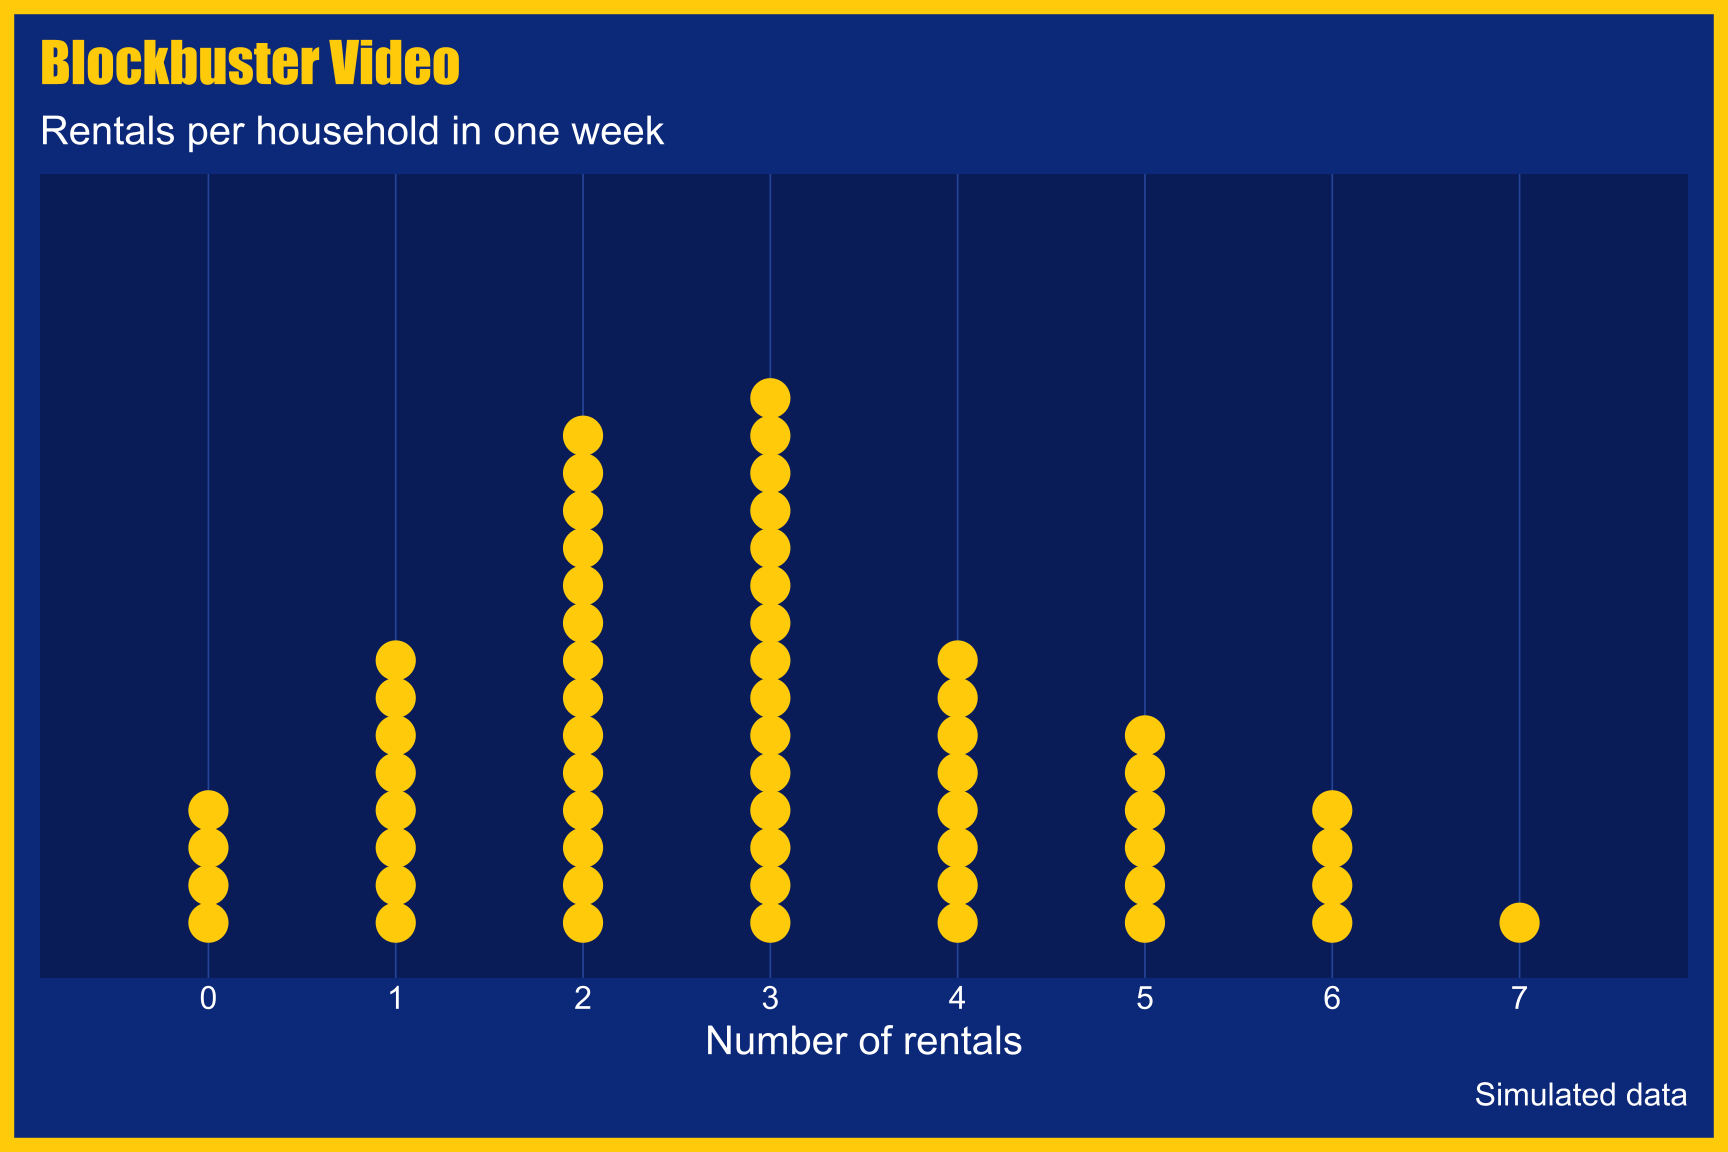
Read more in the function reference.↩︎