24 Ridgeline plots
TipTheme:
theme_squeezit()
Graphs in this chapter use fmggp2::theme_squeezit(), built from Squeezit drink bottles on gravel: a gravel background, a red frame and title, red, orange, green, pink, blue, and gold bottle marks, and a Skia title.
24.1 Description
A density plot shows where numbers fall, using a line instead of bars. A ridgeline plot shows one density line for each group,1 each at its own place up the y axis, so we can compare many lines and still read the numbers on the axes.2 We’ll make them with code from ggridges.3
24.2 Set up
PACKAGES:
Bring in the code we’ll use.4
show/hide
install.packages("ggridges")
library(ggridges)
library(ggplot2)
library(dplyr) # for tibble() and data manipulation
DATA:
Squeezit was a sweet drink from General Mills that came in a small bottle you could press with your hand, made to look like a little person, and every flavor came in its own color. We’ll make up5 how many seconds it took kids to press all the drink out of 60 bottles of each of six flavors. Each flavor gets its own mean (avg_seconds).6 A hill is a line that is high in the middle and low on both sides. rgamma() picks each bottle’s time from a hill with a long side to the right.7 The form of that hill is the same (2.5) for every flavor.8 Starting with set.seed()9 means you’ll get the same 360 bottles every time you run the code below.
show/hide
set.seed(1998) # same 360 bottles every time the code runs
squeezit_drinks <- tibble(
  bottle_id = 1:360, # 360 different bottles, one row each
  flavor = rep(c("Tropical", "Blue raspberry", "Strawberry", "Green punch", "Orange", "Cherry"),
              each = 60) # 60 bottles of each flavor
  ) |>
  mutate(
    flavor = factor(flavor, levels = c("Cherry", "Orange", "Green punch", "Strawberry",
                                       "Blue raspberry", "Tropical")), # fastest to slowest
    avg_seconds = c(Tropical = 40, `Blue raspberry` = 32, Strawberry = 26, `Green punch` = 22,
                    Orange = 18, Cherry = 12)[as.character(flavor)], # average seconds to finish a bottle
    seconds_to_finish = pmax(1, # at least one second
      round(rgamma(n(), shape = 2.5,
                   scale = avg_seconds / 2.5))) # skewed right around each average
    ) |>
  select(bottle_id, flavor, seconds_to_finish)
glimpse(squeezit_drinks)
#> Rows: 360
#> Columns: 3
#> $ bottle_id         <int> 1, 2, 3, 4, 5, 6, 7, 8…
#> $ flavor            <fct> Tropical, Tropical, Tr…
#> $ seconds_to_finish <dbl> 55, 18, 48, 11, 23, 94…
24.3 Distribution
Ridgeline plots put one density line above the next for each group, which makes them good for comparing many groups at once. All six flavors here come from the same kind of rule:10 most bottles have nothing left in them after a short time, and a few take a long time. What changes from flavor to flavor is how far the hill reaches along the x axis.11 Below we’ll move from the bottles, to a graph, to the rule behind it.12
COUNT IT:
Start with the first five tropical bottles.
show/hide
head(squeezit_drinks, 5)These five bottles took between 11 and 55 seconds. The median is the middle number when you put all the numbers in order. The numbers below13 show that the mean is higher than the median for every flavor (a sign of a long side to the right),14 and that how far bottles usually fall from the mean (sd)15 grows with the mean. sd as a part of the mean (cv)16 stays between about 0.54 and 0.72 for every flavor.
show/hide
squeezit_drinks |>
  group_by(flavor) |>
  summarise(mean = mean(seconds_to_finish),
            median = median(seconds_to_finish),
            sd = sd(seconds_to_finish), cv = sd / mean)
DRAW IT:
The ridgeline plot below adds a line at each flavor’s median (quantile_lines = TRUE with quantiles = 2).17 Every hill has its high point18 on the left and a long side to the right. Moving up from cherry to tropical, the high points move right and the long sides get longer in general (strawberry’s reaches farthest), but the form stays the same (the extra small high points, like the one in the tropical hill, come from chance, because we have only 60 bottles of each flavor).19 Since no bottle can take less than 0 seconds, from = 0 starts each hill at 0.
show/hide
ggplot(squeezit_drinks, aes(x = seconds_to_finish, y = flavor, fill = flavor)) +
  ggridges::geom_density_ridges(alpha = 2/3, quantile_lines = TRUE,
    quantiles = 2, color = "#F5F5F5", from = 0, show.legend = FALSE) +
  labs(x = "Seconds to finish", y = NULL)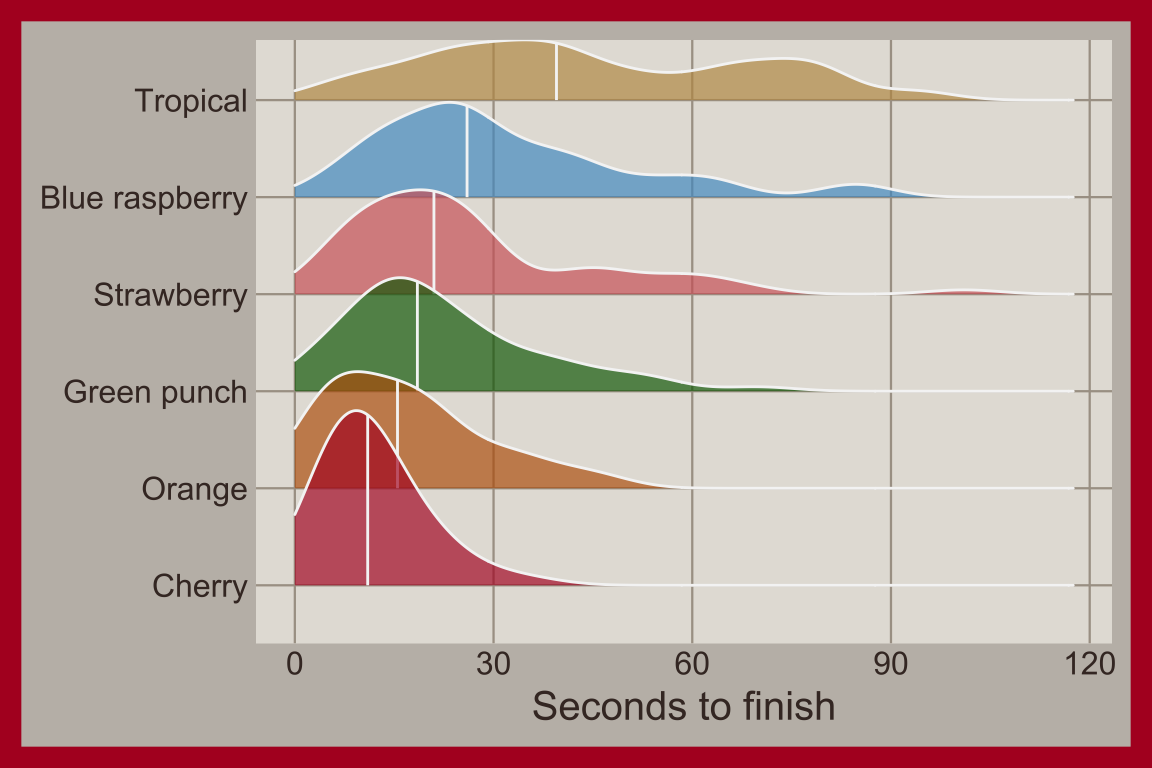
NAME IT:
Each flavor’s bottles come from a hill with a long side to the right20 that has the same number for its form (\(k\)) and its own number for how far it reaches (\(\theta\)):21
\[ X_{\text{flavor}} \sim \text{Gamma}(k = 2.5, \; \theta_{\text{flavor}}), \quad \theta = \frac{\text{avg seconds}}{2.5} \]
The mean of this hill is \(k\theta\) and how far numbers usually fall from the mean is \(\sqrt{k}\,\theta\), so the second as a part of the first is \(1 / \sqrt{k} = 1 / \sqrt{2.5} \approx 0.63\) no matter the flavor.22 That’s why every cv number is close to 0.63 (chance moves them from 0.54 to 0.72) and why the hills all have the same form: changing \(\theta\) makes a hill reach farther or less far along the x axis without changing its form. The Talkboy messages in Chapter 3 came from the same kind of rule, but with a different form number (shape = 4). Try giving one flavor a larger shape in rgamma(), and its hill will come closer to being the same on both sides.23
24.4 Grammar
CODE:
Make the words around the graph24 with
labs()Start the graph with
ggplot()and give itdataPut
seconds_to_finishon thexaxisPut
flavoron theyaxis, and give eachflavorits own color withfillAdd
ggridges::geom_density_ridges()on top25 (withalphaset to2/3, andfrom = 0so no hill starts below 0 seconds)Take away the key26 with
show.legend = FALSE
show/hide
labs_ridges <- labs(
  title = "Squeezit",
  caption = "Simulated data",
  subtitle = "Seconds to squeeze out a whole bottle",
  x = "Seconds to finish",
  y = "Flavor", fill = "Flavor")
ggp2_ridges <- ggplot(data = squeezit_drinks,
       aes(x = seconds_to_finish,
           y = flavor,
        fill = flavor)) +
  ggridges::geom_density_ridges(alpha = 2/3, from = 0,
      show.legend = FALSE)
ggp2_ridges +
  labs_ridges
GRAPH:
Ridgeline plots are very good for comparing where numbers fall27 from one group to the next.
The levels of a categorical variable.↩︎
Unlike overlapping density plots, each group’s curve keeps its own baseline, so the axes stay easy to interpret.↩︎
The
ggridgespackage.↩︎Install and load the packages.↩︎
Simulate.↩︎
The average number of seconds to finish a bottle.↩︎
rgamma()draws values from a right skewed gamma distribution withscale = avg_seconds / 2.5.↩︎The same
shape(2.5) for every flavor.↩︎Setting the random seed.↩︎
The same kind of distribution.↩︎
The scale.↩︎
The formula.↩︎
Summary statistics.↩︎
Right skew.↩︎
The standard deviation.↩︎
The coefficient of variation, the ratio of the standard deviation to the mean.↩︎
A quantile line.
quantiles = 2splits each curve into two halves at the median.↩︎A peak, or mode.↩︎
Random noise from a small sample.↩︎
A gamma distribution with a shared shape and its own scale.↩︎
The shape (\(k\)) and scale (\(\theta\)) parameters.↩︎
The ratio of the standard deviation to the mean.↩︎
More symmetric.↩︎
Labels.↩︎
Add the
ggridges::geom_density_ridges()layer.↩︎The legend.↩︎
Continuous distributions.↩︎