15 Stacked densities
TipTheme:
theme_netscape()
Graphs in this chapter use fmggp2::theme_netscape(), modeled on the Netscape Navigator logo: a night sky background, a teal frame, a glowing teal title, and teal, aurora green, sea glass, and deep teal marks, and a Times New Roman title.
15.1 Description
Density graphs are typically used to visualize the distribution of a single variable, but stacked density graphs are great for visualizing how proportions vary across numeric (continuous) variables.
15.2 Set up
PACKAGES:
Install packages.
show/hide
library(ggplot2)
library(dplyr) # for tibble() and data manipulation
DATA:
In 1996, most people opened Netscape Navigator over a dial up modem, and the modem you owned set how fast the web loaded. We’ll simulate 600 browsing sessions in two steps. First, sample() decides which modem each session used (14.4k, 28.8k, or 56k). Then rnorm() draws the connection speed from that modem’s own normal distribution: no modem ever connects at its full rated speed, and phone line noise spreads the speeds out. Setting the seed with set.seed() means you’ll get the same 600 sessions every time you run the code below.
show/hide
set.seed(1996) # same 600 sessions every time the code runs
modem_sessions <- tibble(
  session_id = 1:600, # 600 different dial up sessions, one row each
  modem = sample(
    c("14.4k", "28.8k", "56k"), 600, # one modem for each session
    replace = TRUE,
    prob = c(0.25, 0.45, 0.30) # 28.8k is the most common
    ),
  speed_kbps = round(
    case_when( # real speeds fall short of each modem's rating
      modem == "14.4k" ~ rnorm(600, mean = 13, sd = 1.2),
      modem == "28.8k" ~ rnorm(600, mean = 26, sd = 2.5),
      TRUE ~ rnorm(600, mean = 44, sd = 5) # 56k modems vary the most
      ),
    1 # one decimal place
    )
  ) |>
  mutate(modem = factor(modem, levels = c("14.4k", "28.8k", "56k"))) # slowest to fastest
dplyr::glimpse(modem_sessions)
#> Rows: 600
#> Columns: 3
#> $ session_id <int> 1, 2, 3, 4, 5, 6, 7, 8, 9, 10…
#> $ modem      <fct> 56k, 28.8k, 28.8k, 28.8k, 56k…
#> $ speed_kbps <dbl> 44.6, 24.4, 28.9, 28.7, 39.1,…
15.3 Distribution
A filled density graph answers a different question than a regular density plot. Instead of asking “how common is each speed?”, it asks “at this speed, which modem is a session most likely using?” The answer depends on two things: how common each modem is, and how its speeds are spread out. Below we’ll move from the sessions, to a picture, to the formula.
COUNT IT:
Start with the first six sessions.
show/hide
head(modem_sessions, 6)The 28.8k sessions connect in the mid to high 20s, and the 56k sessions connect around 40 to 45. Counting all 600 sessions shows how common each modem is overall.
show/hide
modem_sessions |>
  count(modem) |>
  mutate(share = n / sum(n))
Now zoom in on the sessions that connected between 30 and 36 kbps. This is the overlap zone: a fast 28.8k connection and a slow 56k connection both land here. The two modems split these sessions roughly in half.
show/hide
modem_sessions |>
  filter(speed_kbps >= 30, speed_kbps < 36) |>
  count(modem) |>
  mutate(share = n / sum(n))
DRAW IT:
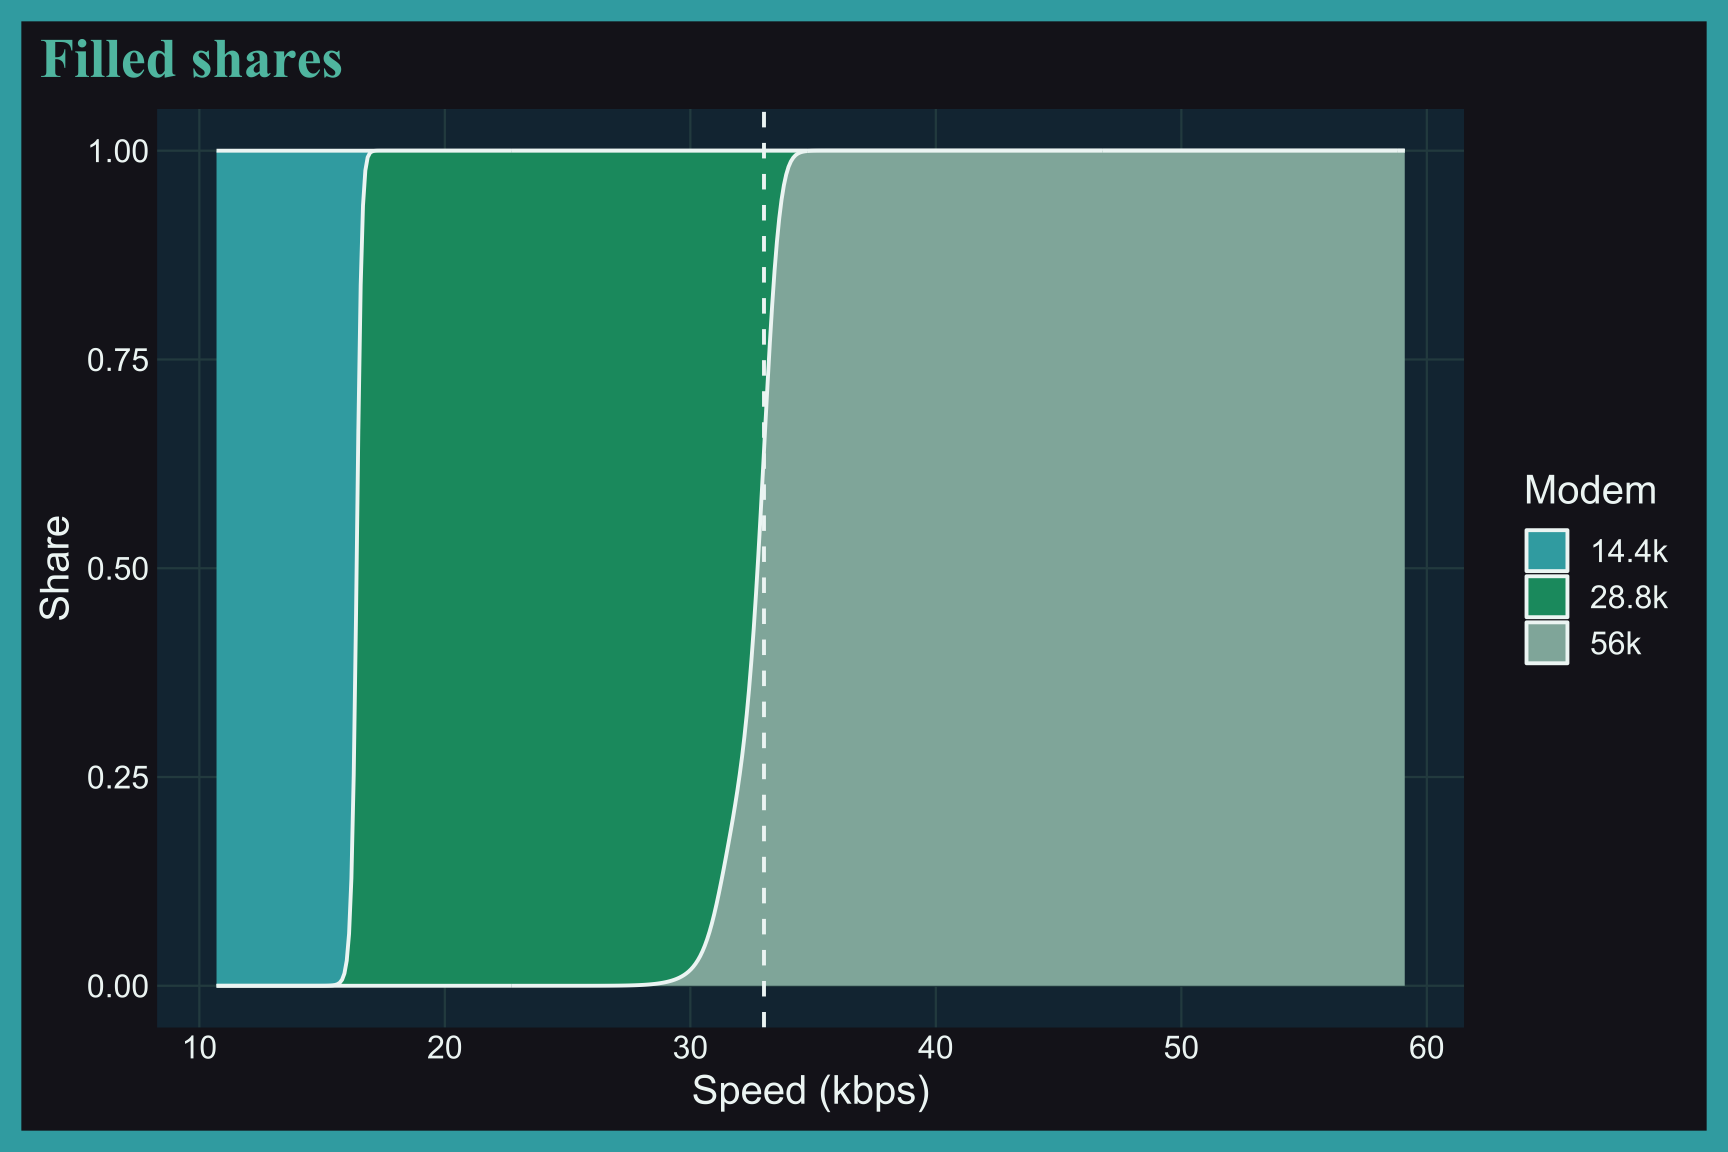
Below are two views of the same 600 sessions. The first stacks the count densities, so the height of each color at a speed is about how many sessions fall in a 1 kbps wide slice there.1 The second uses position = "fill", which stretches every vertical slice to 100% and turns the counts into shares. The dashed line at 33 kbps sits in the overlap zone, where the filled graph splits between 28.8k and 56k.
show/hide
ggplot(modem_sessions, aes(x = speed_kbps, after_stat(count), fill = modem)) +
  geom_density(position = "stack") +
  geom_vline(xintercept = 33, linetype = "dashed") +
  labs(title = "Stacked counts", x = "Speed (kbps)", y = "Sessions per kbps",
    fill = "Modem")

ggplot(modem_sessions, aes(x = speed_kbps, after_stat(count), fill = modem)) +
  geom_density(position = "fill") +
  geom_vline(xintercept = 33, linetype = "dashed") +
  labs(title = "Filled shares", x = "Speed (kbps)", y = "Share",
    fill = "Modem")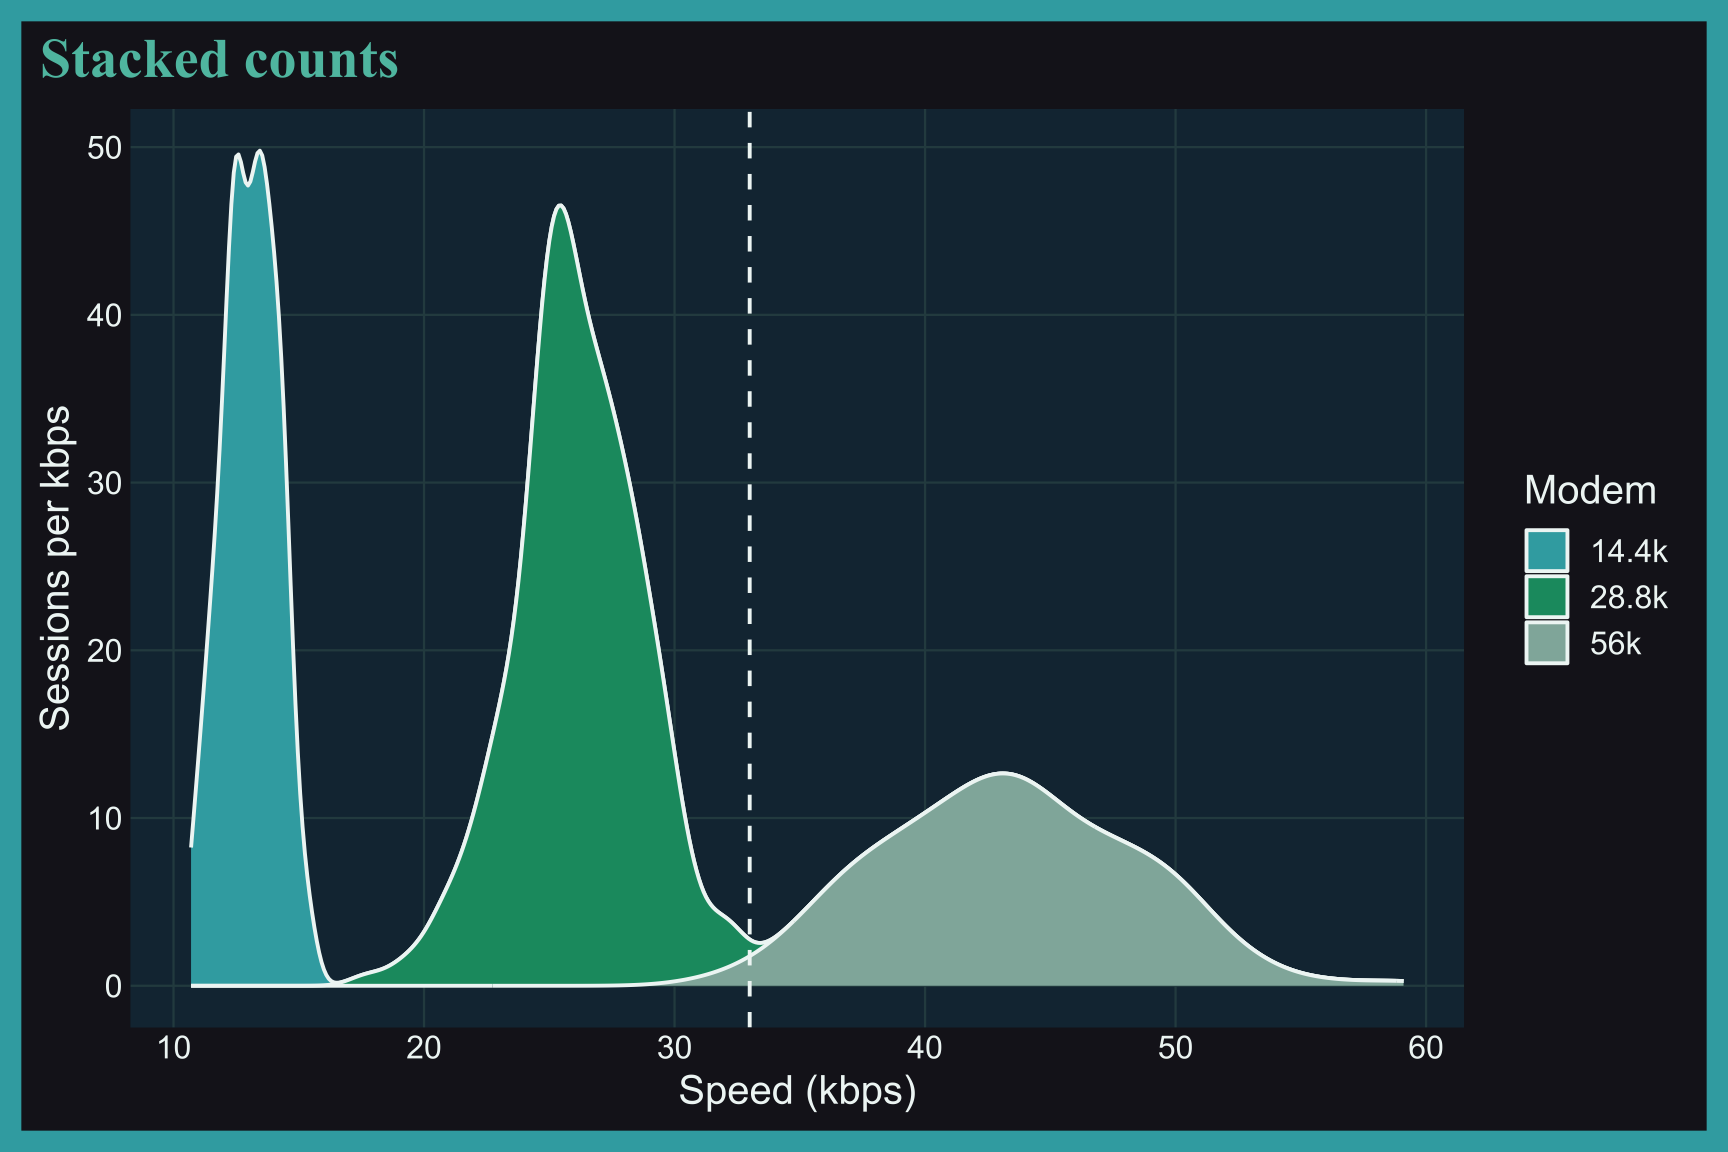
NAME IT:
The speeds come from a mixture of three normal distributions, one per modem \(k\), each with its own share of the sessions (\(\pi_k\)):
\[ f(x) = \sum_{k} \pi_k \, \text{Normal}(x; \, \mu_k, \sigma_k) \]
with \(\pi = (0.25, 0.45, 0.30)\), \(\mu = (13, 26, 44)\), and \(\sigma = (1.2, 2.5, 5)\). The filled density shows each modem’s slice of that sum, which is Bayes’ theorem drawn as a picture:
\[ P(\text{modem } k \mid x) = \frac{\pi_k \, \text{Normal}(x; \, \mu_k, \sigma_k)}{f(x)} \]
At 33 kbps, the 14.4k curve is essentially zero, so the share splits between the other two: \(0.45 \times \text{Normal}(33; 26, 2.5)\) for 28.8k and \(0.30 \times \text{Normal}(33; 44, 5)\) for 56k. That works out to about 40% for 28.8k and 60% for 56k, close to the split the filled graph shows at the dashed line. Try raising the 56k share in sample() and the 56k band at 33 kbps grows, even though no modem got faster.
15.4 Grammar
CODE:
Create labels with
labs()Initialize the graph with
ggplot()and providedataMap the
speed_kbpsto thexand addafter_stat(count)Map
modemtofillInside the
geom_density()function, setpositionto"fill"
show/hide
labs_fill_density <- labs(
  title = "Dial up connections",
  caption = "Simulated data",
  subtitle = "Share of sessions from each modem at every speed",
  x = "Connection speed (kbps)",
  fill = "Modem")
ggp2_fill_density <- ggplot(data = modem_sessions,
       aes(x = speed_kbps,
           after_stat(count),
          fill = modem)) +
      geom_density(position = "fill")
ggp2_fill_density +
  labs_fill_density
GRAPH:
The count density,
after_stat(count), is the density multiplied by the number of sessions in the group. Its units are sessions per kbps, and the area under each curve equals the number of sessions in that modem’s group.↩︎