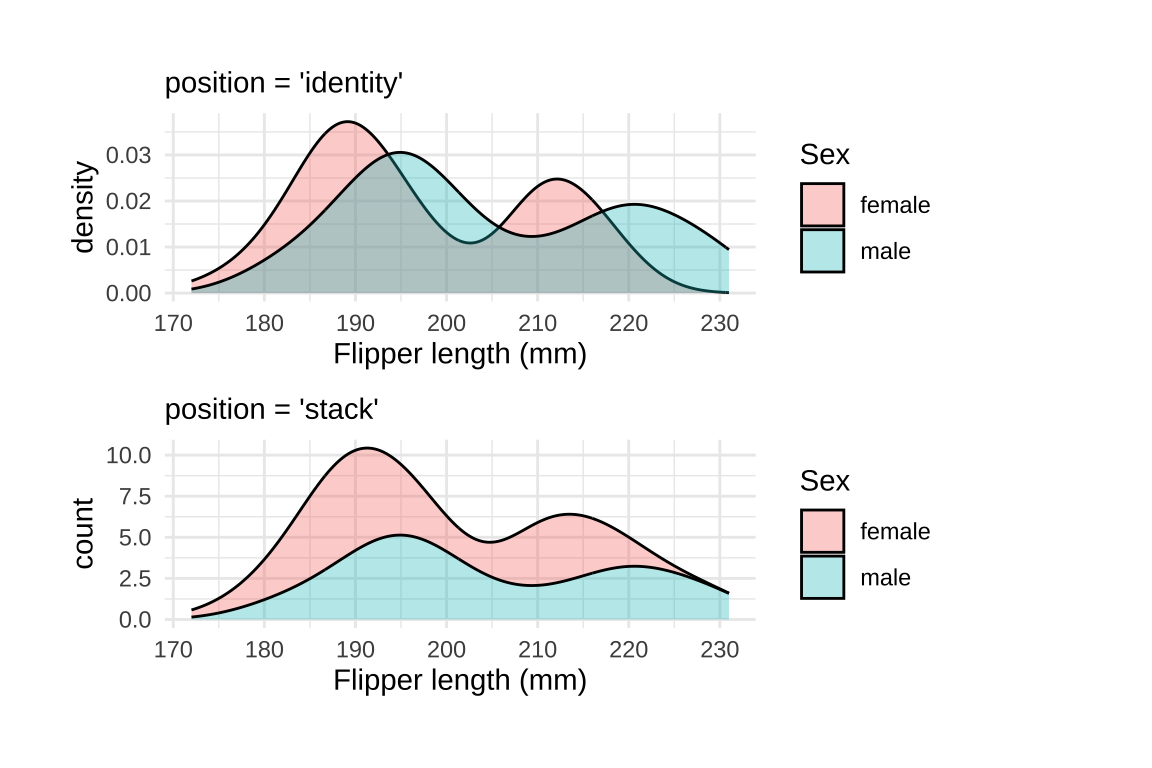
23 Overlapping density plot
TipTheme:
theme_pager()
Graphs in this chapter use fmggp2::theme_pager(), built from a RIM 950 two-way pager: a concrete background, a charcoal frame and title, a pale LCD panel, charcoal, orange, and slate marks, and an Arial Black title.
23.1 Description
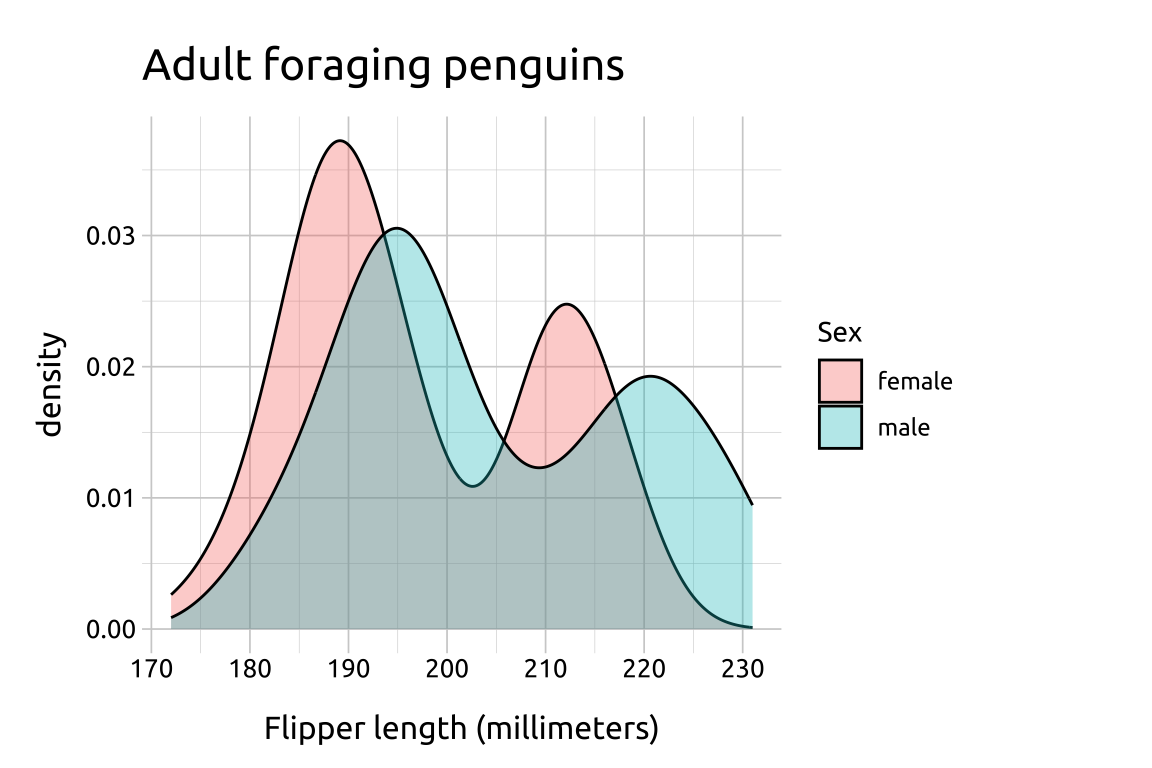
Density plots are smoothed version(s) of histogram(s). They are great for comparing the distributions of a continuous variable across the levels of a categorical variable.
geom_density() creates a kernel density estimate. The default position argument is "identity", which takes the data as is (each group’s curve starts at 0, so the curves overlap). However, we can change position to "stack" to put each group’s curve on top of the one below it.
23.2 Set up
PACKAGES:
Install packages.
show/hide
library(ggplot2)
library(dplyr) # for tibble() and data manipulation
DATA:
In 1998, Research In Motion (RIM) released the Inter@ctive Pager 950, a two way pager with a tiny keyboard you typed on with your thumbs (and the ancestor of the BlackBerry). Its main rival was the Motorola PageWriter. We’ll simulate 300 messages: 180 sent from a RIM 950 and 120 sent from a PageWriter. Each pager model gets its own normal distribution of message lengths in characters (rnorm()), and RIM 950 messages are both longer and more consistent. Setting the seed with set.seed() means you’ll get the same 300 messages every time you run the code below.
show/hide
set.seed(1998) # same 300 messages every time the code runs
pager_messages <- tibble(
  msg_id = 1:300, # 300 different messages, one row each
  model = rep(c("RIM 950", "PageWriter"), times = c(180, 120)) # 180 from the RIM, 120 from the PageWriter
  ) |>
  mutate(
    model = factor(model, levels = c("RIM 950", "PageWriter")),
    msg_length = round(
      if_else(model == "RIM 950",
        rnorm(n(), mean = 45, sd = 8), # RIM messages run longer (about 45 characters)
        rnorm(n(), mean = 30, sd = 10) # PageWriter messages run shorter (about 30)
        )
      )
    )
dplyr::glimpse(pager_messages)
#> Rows: 300
#> Columns: 3
#> $ msg_id     <int> 1, 2, 3, 4, 5, 6, 7, 8, 9, 10…
#> $ model      <fct> RIM 950, RIM 950, RIM 950, RI…
#> $ msg_length <dbl> 31, 32, 57, 23, 56, 40, 43, 4…
23.3 Distribution
Overlapping and stacked density plots can tell two different stories about the same data. By default, each group’s curve covers an area of 1, which hides the fact that one group might be much bigger than the other. Our two pager models aren’t the same size (180 messages vs. 120), so the choice matters here. Below we’ll move from the messages, to a picture, to the formula.
COUNT IT:
Start with the first five messages (all sent from a RIM 950).
show/hide
head(pager_messages, 5)These five messages range from 23 to 57 characters. The summary below compares the two pager models: the RIM 950 has more messages, longer messages on average, and a smaller standard deviation.
show/hide
pager_messages |>
  group_by(model) |>
  summarise(messages = n(), mean = mean(msg_length),
            sd = sd(msg_length))
DRAW IT:
A bar model shows the two groups as parts of all 300 messages. The RIM 950 takes up 60% of the bar and the PageWriter takes up 40%.
show/hide
pager_messages |>
  count(model) |>
  ggplot(aes(x = n, y = "300 messages", fill = model)) +
  geom_col(position = position_stack(reverse = TRUE)) +
  geom_text(aes(label = n), color = "#C3D7D9",
    position = position_stack(vjust = 0.5, reverse = TRUE)) +
  labs(x = "Messages", y = NULL, fill = "Pager model")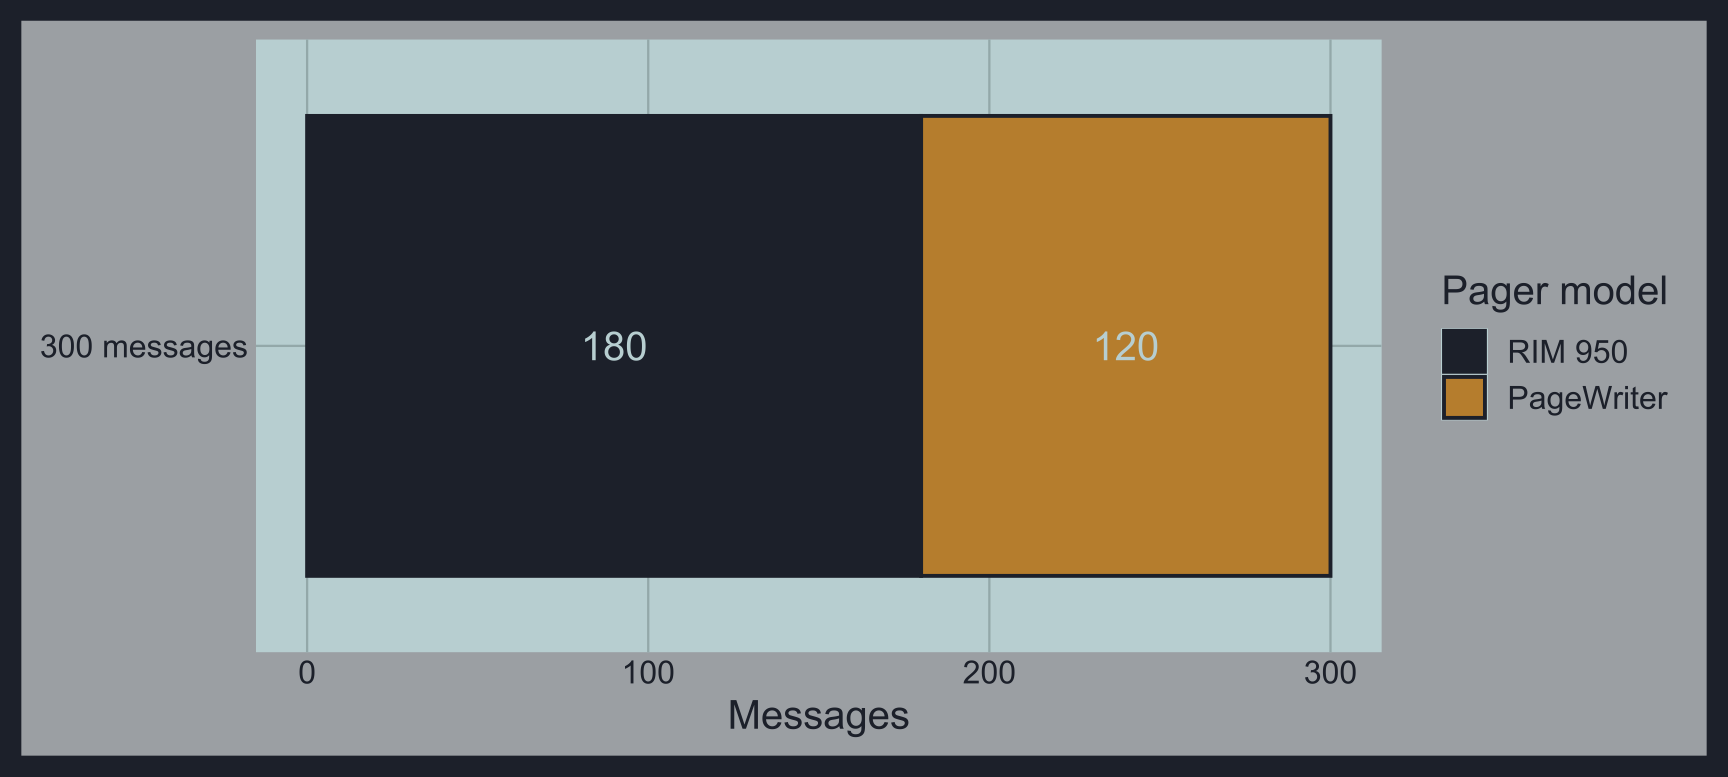
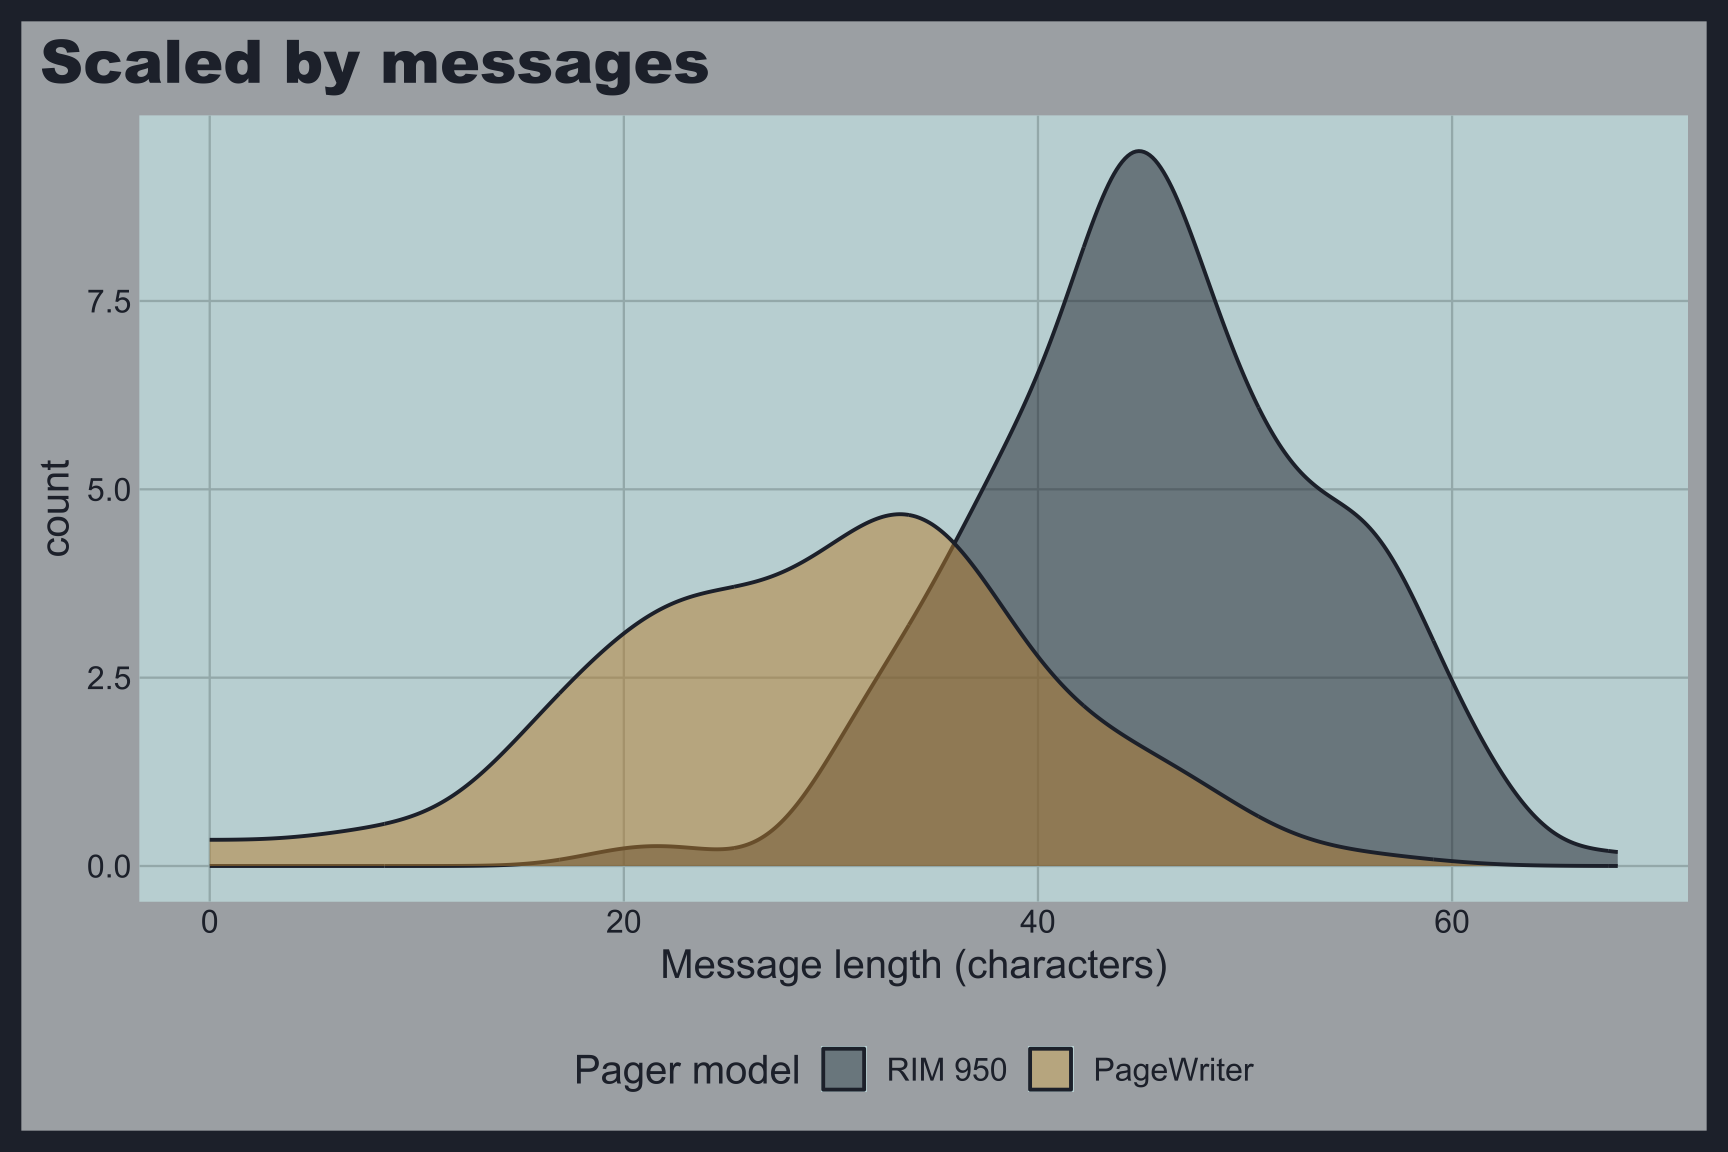
The two graphs below show why the bar model matters. On the left, the default densities each cover an area of 1, so the PageWriter curve looks almost as big as the RIM 950 curve. On the right, after_stat(count) scales each curve by its number of messages, so the RIM 950 curve is 1.5 times the size of the PageWriter curve, just like the bar model.
show/hide
ggplot(pager_messages, aes(x = msg_length, fill = model)) +
  geom_density(alpha = 1/2, bounds = c(0, Inf)) +
  labs(title = "Area of 1 each", x = "Message length (characters)",
    fill = "Pager model") +
  theme(legend.position = "bottom")

ggplot(pager_messages, aes(x = msg_length, after_stat(count),
    fill = model)) +
  geom_density(alpha = 1/2, bounds = c(0, Inf)) +
  labs(title = "Scaled by messages", x = "Message length (characters)", y = "count",
    fill = "Pager model") +
  theme(legend.position = "bottom")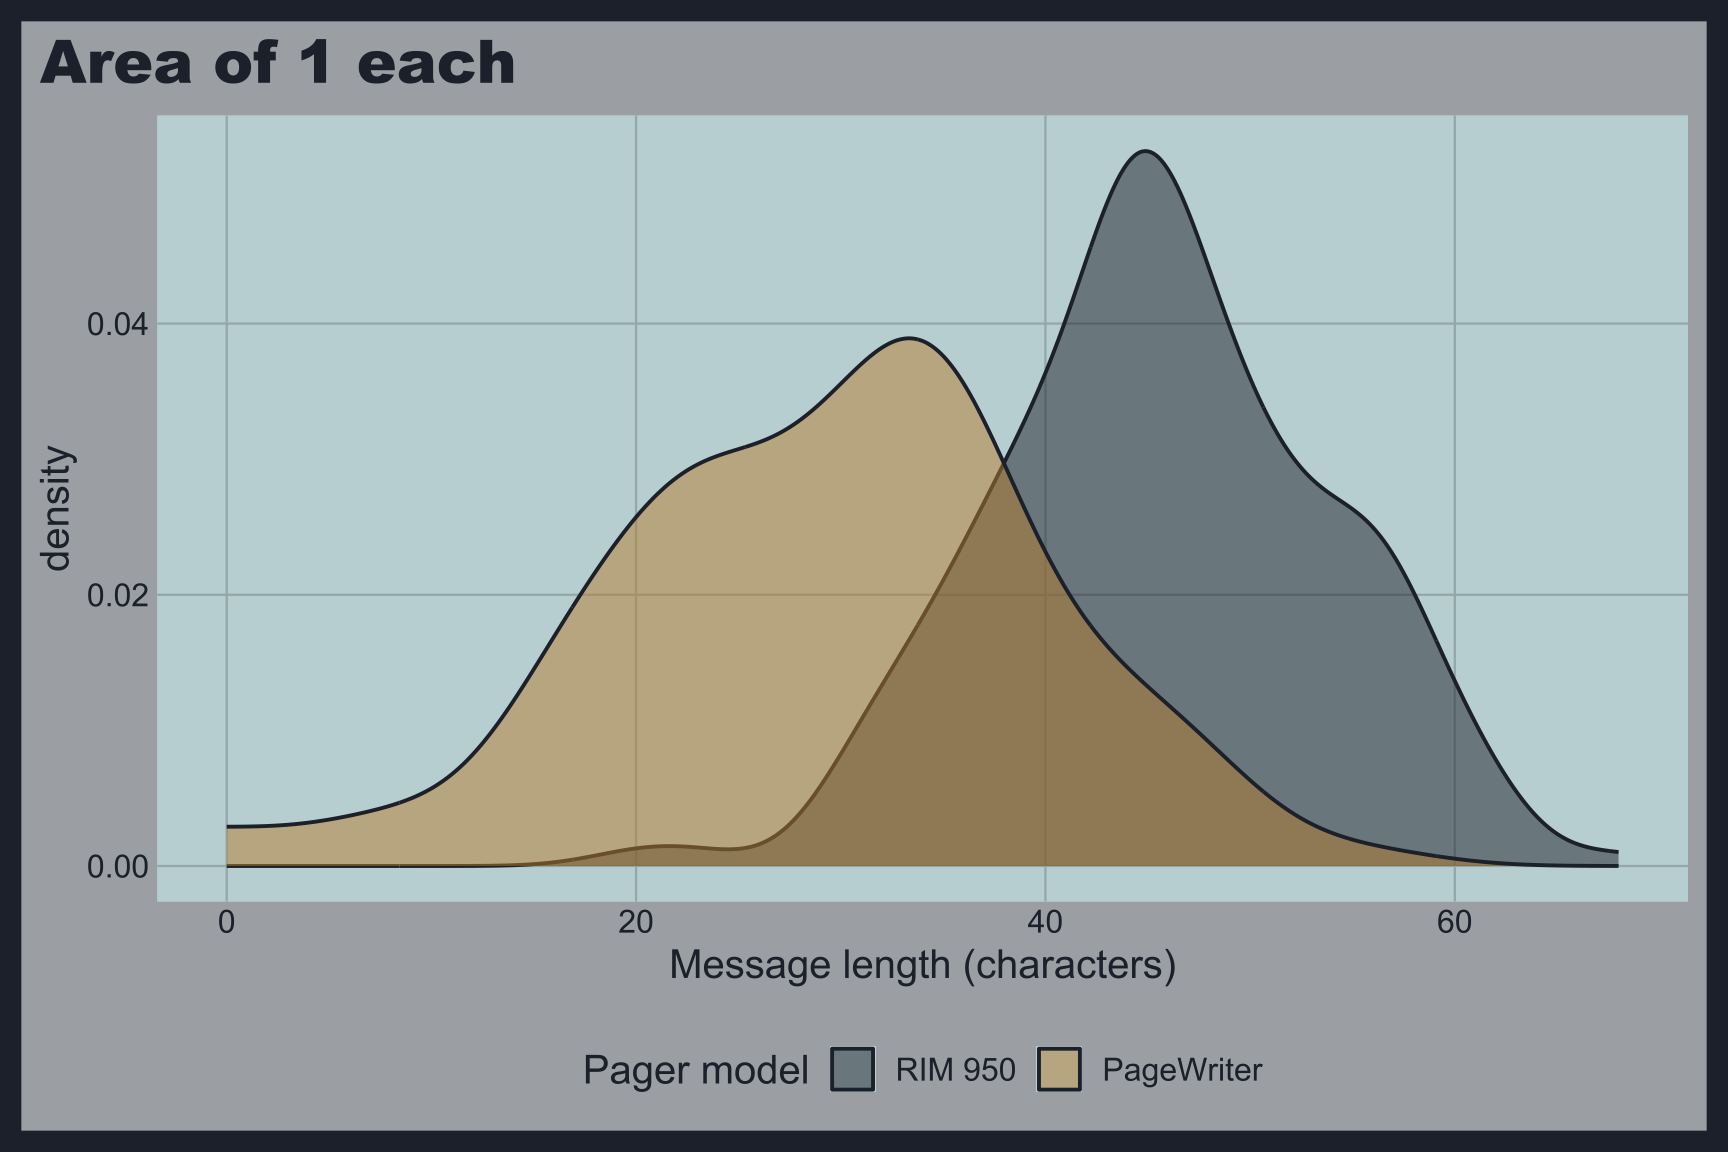
NAME IT:
Each pager model has its own normal distribution, and the two are mixed in proportion to their number of messages:
\[ f(x) = 0.6 \cdot \text{Normal}(x;\, 45, 8) + 0.4 \cdot \text{Normal}(x;\, 30, 10) \]
geom_density() estimates each group’s curve so that its area is 1 (each \(\text{Normal}\) term on its own). after_stat(count) multiplies each curve by its group size, so the two curves have areas of 180 and 120. Stacking those count curves (position = "stack") adds them together into \(300 \times f(x)\), the curve for all 300 messages. Try making the two groups the same size in rep() and the two graphs above will look almost identical.
23.4 Grammar
CODE:
Create labels with
labs()Initialize the graph with
ggplot()and providedataMap the
msg_lengthto thexandmodeltofillAdd the
geom_density()Set the
alphato1/3(to handle the overlapping areas)Set
boundstoc(0, Inf)(a message can’t have fewer than 0 characters)
show/hide
labs_ovrlp_density <- labs(
  title = "Two way pager messages",
  caption = "Simulated data",
  x = "Message length (characters)",
  fill = "Pager model")
ggp2_ovrlp_density <- ggplot(data = pager_messages,
       aes(x = msg_length,
           fill = model)) +
      geom_density(alpha = 1/3, bounds = c(0, Inf))
ggp2_ovrlp_density +
  labs_ovrlp_density
GRAPH:
A downside of density plots is a y axis that’s hard to interpret
Make density area mostly transparent to handle over-plotting.
23.5 More info
ggplot2 has multiple options for overlapping density plots, so which one to use will depend on how you’d like to display the relative distributions in your data. We’ll cover three options below:
23.5.1 "stack"
If we change the position to "stack" we can see the smoothed estimates are ‘stacked’ on top of each other (and the y axis shifts slightly).
show/hide
labs_stack_density <- labs(
    title = "Two way pager messages",
    caption = "Simulated data",
    x = "Message length (characters)",
    fill = "Pager model")
ggp2_stack_density <- ggplot(data = pager_messages,
    mapping = aes(x = msg_length,
               fill = model)) +
    geom_density(position = "stack",
                 bounds = c(0, Inf),
                 alpha = 1 / 3)
ggp2_stack_density +
    labs_stack_density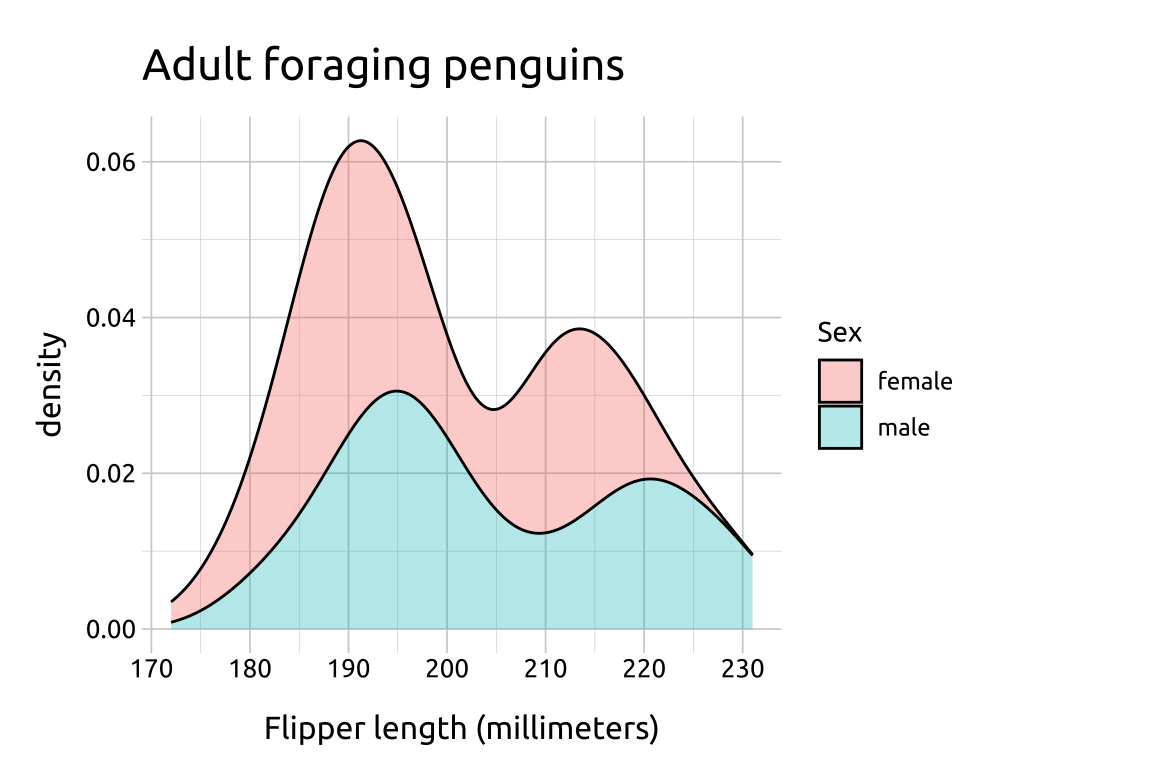
Setting position to 'stack' loses marginal densities: the top curve is the sum of the group densities, not the density of all 300 messages.
23.5.2 after_stat(count)
If we include after_stat(count) as one of our mapped aesthetics, the mapping is postponed until after statistical transformation, and uses the density * n instead of the default density.
show/hide
labs_after_stat_density <- labs(
  title = "Two way pager messages",
  caption = "Simulated data",
  x = "Message length (characters)",
  fill = "Pager model")
ggp2_after_stat_density <- ggplot(data = pager_messages,
       aes(x = msg_length,
           after_stat(count),
           fill = model)) +
      geom_density(position = "stack",
                   bounds = c(0, Inf),
                   alpha = 1/3)
ggp2_after_stat_density +
  labs_after_stat_density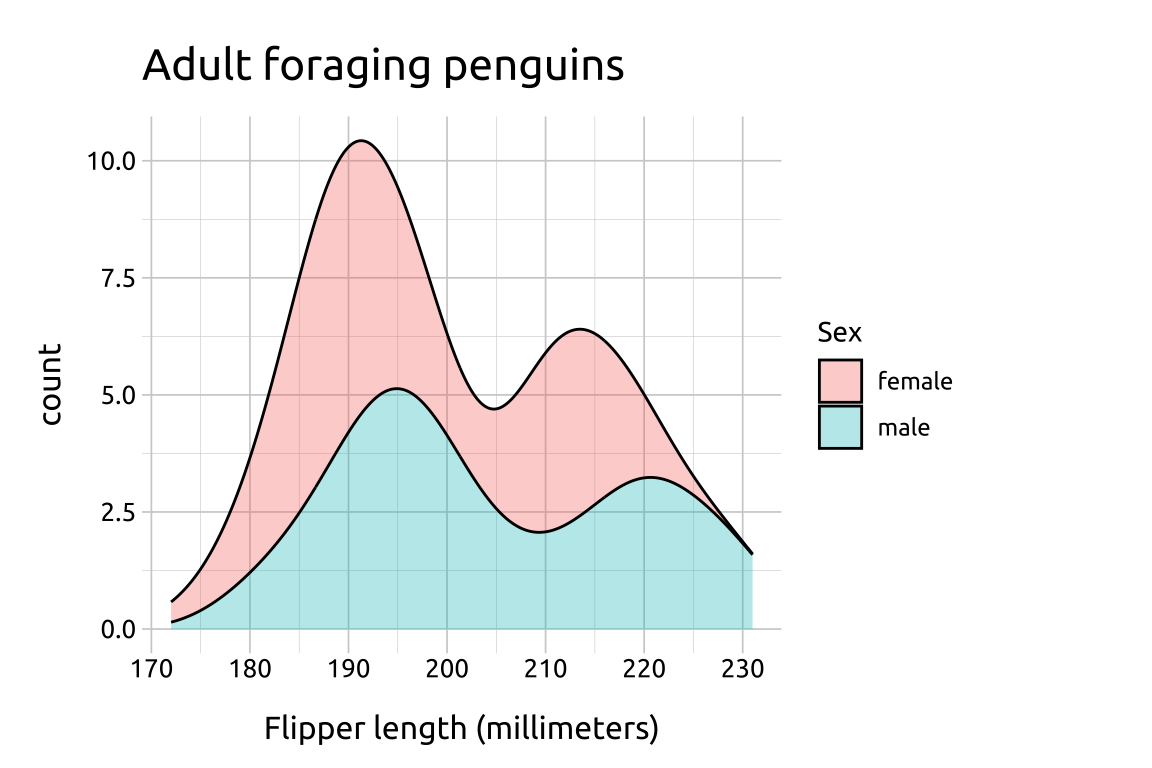
Adding after_stat(count) ‘preserves marginal densities.’, which results in a more interpretable y axis (depending on the audience).
23.5.3 "fill"
Using after_stat(count) with position = "fill" creates a conditional density estimate (each group’s share of the messages at every message length).
show/hide
labs_fill_density <- labs(
  title = "Two way pager messages",
  caption = "Simulated data",
  x = "Message length (characters)",
  y = "Share",
  fill = "Pager model")
ggp2_fill_density <- ggplot(data = pager_messages,
       aes(x = msg_length,
           after_stat(count),
           fill = model)) +
      geom_density(position = "fill",
                   bounds = c(0, Inf),
                   alpha = 1/3)
ggp2_fill_density +
  labs_fill_density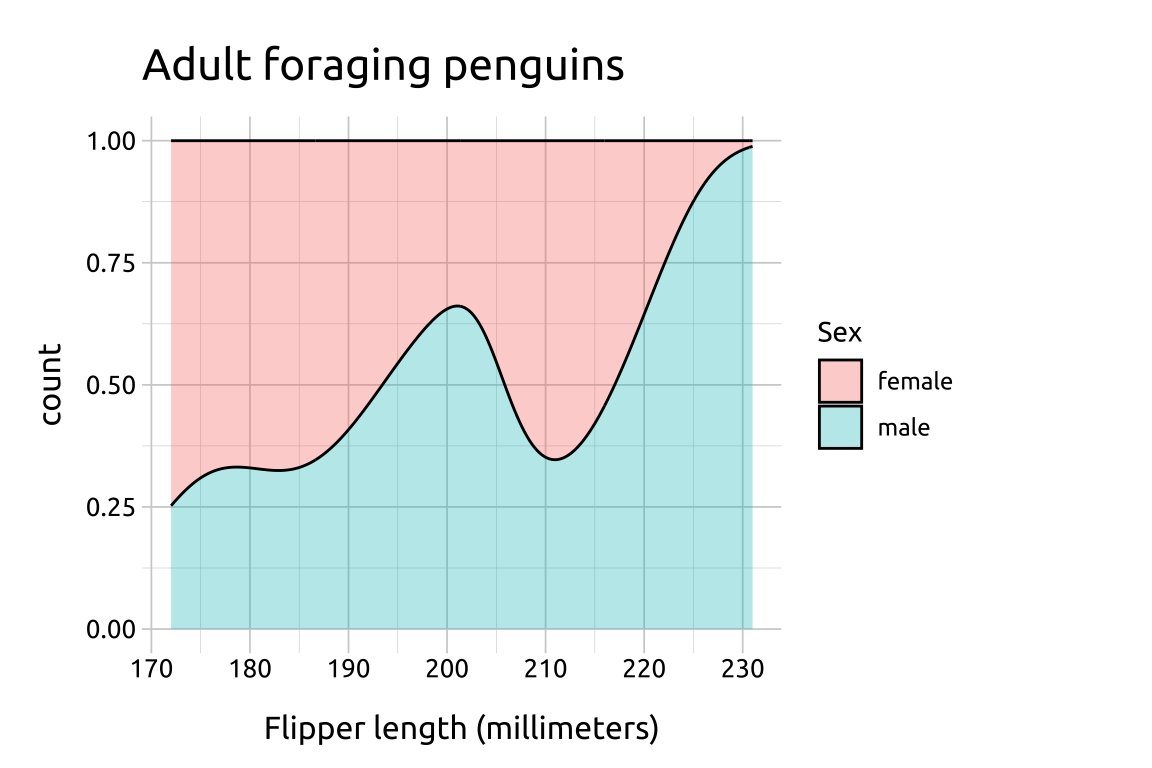
This results in a y axis ranging from 0 to 1, and the area filled with the relative proportional values.